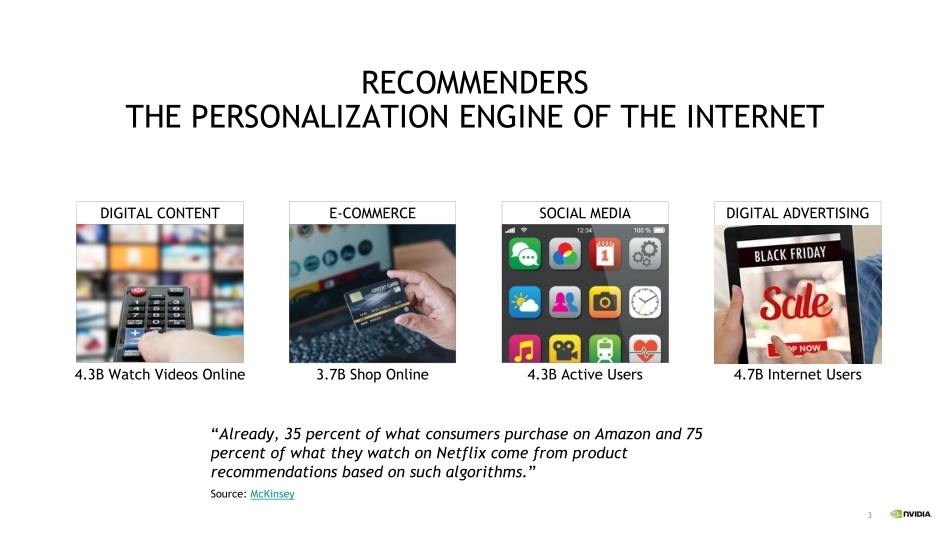
Related Session in GTC 2022Merlin HugeCTR: 由GPU加速的推荐系统训练和推理 [S41352] - Minseok Lee | NVIDIA MERLIN 推荐系统团队高级经理Merlin HugeCTR: 使用GPU Embedding 缓存的分布式分层推理参数服务器 [S41126] - Yingcan Wei, Fan Yu, Matthias Langer | NVIDIABuilding and Deploying Recommender Systems Quickly and Easily with NVIDIA Merlin [S41119] – Even Oldridge, Senior Manager, Merlin Recommender Systems Team, NVIDIAGetting startedHugeCTR @ NVIDIA.com: https://developer.nvidia.com/nvidia-merlin/hugectrHugeCTR @ GitHub: https://github.com/NVIDIA-Merlin/HugeCTRSuccess stories•Leading Design and Development of the Advertising Recommender System at Tencent:An Interview with Xiangting Kong•Meituan / Optimizing Meituan’s Machine Learning Platform: An Interview with Jun HuangLearn more about HugeCTR•Accelerating Embedding with the HugeCTR TensorFlow Embedding Plugin•HugeCTR Series Part 1:Scaling and Accelerating large Deep Learning Recommender Systems(CN) HugeCTR 系列第 1 部分:扩展和加速大型深度学习推荐系统•HugeCTR Series Part 2:Training large Deep Learning Recommender Models with Merlin HugeCTR’s Python APIs(CN) HugeCTR 系列第 2 部分:使用 Merlin HugeCTR 的 Python API 训练大型深度学习推荐模型•HugeCTR Parameter Server Series Part 1: Introduction to Hierarchical Parameter ServerWe are Hiring(Full Time & Intern) : C++ Engineer, CUDA Engineer, Recommendation System Algorithm ResearcherPlease email your Resume to: sh-recruitment@nvidia.comHugeCTRResourcesMERLIN HUGECTR: GPU-ACCELERATED RECOMMENDER SYSTEM TRAINING AND INFERENCEJERRY SHI3SOCIAL MEDIADIGITAL ADVERTISINGE-COMMERCEDIGITAL CONTENTRECOMMENDERSTHE PERSONALIZATION ENGINE OF THE INTERNET 4.3B Active Users4.3B Watch Videos Online3.7B Shop Online4.7B Internet Users“Already, 35 percent of what consumers purchase on Amazon and 75 percent of what they watch on Netflix come from product recommendations based on such algorithms.”Source: McKinsey4NVTabular Pipelines are slow and complexChallengeSolutionInferenceTrainingData LoadingETLUsing common item-by-item loading can be slowHigh throughput to rank more items is difficult while maintaining low latencyEmbedding tables of large deep learning recommender systems can exceed memory GPU-accelerated and easy-to-use ETL pipelines prepares datasets in minutesAsynchronous and GPU-accelerated dataloader for PyTorch and TensorFlow/KerasEasy data and model parallel training allow to scale TB size embeddings High throughput, low-latency production deploymentNVIDIA Merlin is an open-source library to deploy recommender systems end-2-endTritonHugeCTRNVIDIA Merlin addresses Recommender System challenges5AGENDAHugeCTR OverviewHugeCTR InferenceHugeCTR Sparse Operation KitHUGECTR OVERVIEWHUGECTR: SCALABLE, ACCELERATED RECSYS TRAININGhttps://github.com/NVIDIA-Merlin/HugeCTR▪ An open-source framework to accelerate the training of CTR estimation models on NVIDIA GPUs.▪ Written in CUDA C++ and highly exploits GPU-accelerated libraries such as cuBLAS, cuDNN, and NCCL▪ Provide a high-level, Keras-like Python API▪ Continue to power NVIDIA’s MLPerf DLRM submission▪ Designed for training recommender models at scale where gigantic embedding tables are included▪ Support common models and their variants such as Deep Learning Recommendation Model (DLRM), Wide and Deep, Deep Cross Network, and DeepFM▪ Support GPU-accelerated, concurrent model inference as a Triton backend based on an efficient embedding cache and hierarchical parameter server (HPS)CHALLENGES OF EMBEDDING LAYERMemory Demands and Communication Overhead▪ Challenge 1. Embedding tables may not fit in a single GPU memory, e.g., 100GB, 1TB, etc▪ Solution: Store tables across multiple GPUs (and multiple nodes) ➔ Model Parallelism▪ Challenge 2. Embedding primitives such as table lookup and pooling/reduction operator are memory bound▪ Solution: Fuse such CUDA kernels▪ Challenge 3. Model parallelism requires inter-GPU/inter-node communication▪ Solution: Use NCCL and/or exploit NVLink (or NVSwitch)▪ Common solution for Challenge 1 & 2& 3: Use lower precision such as FP16RECOMMENDER MODEL AT SCALEHugeCTR embedding table can span multiple nodes beyond multiple GPUs Neural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkGPU0GPU1GPU2GPU3GPU4GPU5GPU6GPU7Node 0Neural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkNeural NetworkGPU0GPU1GPU2GPU3GPU4GPU5GPU6GPU7Node 1EmbeddingsCOMMON EMBEDDING PRIMITIVESAll Memory BoundEmbeddingTablesCategoricalfeaturesfea1(multi-hot)fea2fea3fea0(1) Table lookup(2) Pooling/Reduction(3) ConcatenationHUGECTR EMBEDDING LAYERGPU Hash Table + CUDA Kernel FusionEmbeddingTablesCategoricalfeaturesfea1(multi-hot)fea2fea3fea0(1) Hash table lookup(2) In-register reduction & concatenation (one fused kernel)WEIGHT CONVERSION FOR MIXED PRECISION TRAININGFrom FP32 Master Weights to FP16 Weights ▪ In each training iteration, optimizer computes the master weights in FP32▪ To support mixed precision training, FP32 weights must be casted into FP16▪ Currently the optimizer w...




发表评论取消回复